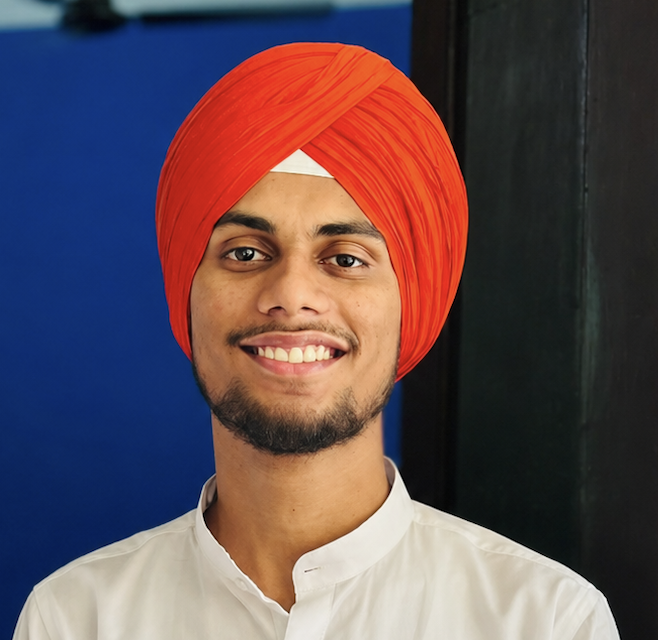
Manpreet Singh

Manpreet Singh

ML Systems Research Intern @ Embedded LLM — Singapore

singhman2005123@gmail.com

01

Bio

I'm Manpreet Singh, a B.E. Computer Engineering student at Thapar Institute (2023–2027, CGPA 9.22) and an ML Systems Research Intern at Embedded LLM, Singapore. I write portable GPU kernels that fuse and accelerate biological and medical foundation models across NVIDIA and AMD hardware, turning order-of-magnitude speedups into clinically and scientifically usable systems.

My goal is simple: make biological foundation models run orders of magnitude faster. This has produced 7 papers, 3 posters, and 2 accepted talks across NeurIPS, ICML, ISCA, COLM, MOML, ACM ICS, ICPP, EurIPS, MLSys, RECOMB, and ISC High Performance.
A cat typing furiously on a laptop, captioned RESEARCH TIME!!!

Fig. 0. The author, mid-rebuttal.

02

Where the work has been accepted

11 / 11 flags planted · 11 venues · 4 continents
PaperPosterTalk
Equator
Fig. 1. Each flag is a venue that accepted the work, planted in the order the acceptances arrived, from home in India. Drag the timeline to replay; hover a city for the paper.
03

News

most recent first
04

Research & Publications

all research →
Change the Metric, Change the Winner: Auditing How We Decide Which Clinical Foundation Model to Deploy in Cancer Pathology
NeurIPS 2026TAE workshop · Trust-AI-EvalEmbedded LLM
paperposterView findings →
From 13 Hours to 4.6: Profiling-Driven Kernel Fusion for TensorNet in Molecular Simulation
MOML 2026 @ MITMolecular ML Conference · SeptemberCambridge, USAEmbedded LLM
paperposterView findings →
From 805 ms to 23 ms: Accelerating State-Space Models for Real-Time ICU Monitoring with Fused Triton Kernels
ICML 2026SD4H workshopSouth KoreaEmbedded LLM
paperposterView findings →
When the LLM-Tuned Stack Misses: An Infrastructure View of Biological Foundation Model Inference Across NVIDIA and AMD
ISCA 2026HotInfra workshopU.S.A.Embedded LLM
papertalkView findings →
Deploying Clinical Language and Vision-Language Models Where the Data Lives: An Energy-Aware, Cross-Vendor Protocol for On-Premises Healthcare AI
COLM 2026DAIH workshopSan Francisco, USAEmbedded LLM
paperposterView findings →
Error-Bounded Fused Attention Compression for Long-Context Genomic Foundation Models Across Heterogeneous GPUs
ICPP 2026DC4AI workshopSingaporeEmbedded LLM
paperposterView findings →
Accelerating Molecular Simulations with Triton: Fused GPU Kernels for TensorNet Neural Potentials
EurIPS 2025SimBioChem workshopDenmark· also reviewerEmbedded LLM
paperposterView findings →
From 805 ms to 23 ms: Accelerating State-Space Models for Real-Time ICU Monitoring with Fused Triton Kernels
ACM ICS 2026Arch4Health · talkUnited KingdomEmbedded LLM
talkView talk →
BioTriton: Portable Cross-Vendor GPU Kernels for High-Throughput Bioinformatics via OpenAI Triton
MLSys 2026YPSBellevue, WA, USAEmbedded LLM
posterView findings →
Hardware-Portable Fused GPU Kernels for High-Throughput Biological Foundation Models
RECOMB 2026ARCHGreeceEmbedded LLM
posterView findings →
Portable GPU Kernel Acceleration for Biological Foundation Models & Algorithms using OpenAI Triton
ISC High Performance 2026GermanyEmbedded LLM
posterView findings →
05

Experience

Embedded LLM Oct 2025 — Present Singapore · Remote
ML Systems Research Intern current
  • Led solo research producing 7 papers, 3 posters, and 2 accepted talks across NeurIPS 2026, ICML 2026, MOML 2026, ISCA 2026, COLM 2026, ACM ICS 2026, ICPP 2026, EurIPS 2025, MLSys YPS, RECOMB-ARCH, and ISC High Performance 2026.
  • Building BioTriton, an open-source Triton acceleration library for biology and chemistry workflows across heterogeneous GPU backends.
  • Accelerated ProteinMPNN inference with custom Triton kernels: 1.5× average (1.61× peak), 100% accuracy preserved.
  • Compressed ESM-2 embeddings via TurboQuant: 4× smaller (439MB → 110MB), +46% Recall@10 over FAISS PQ, 10M proteins in 11GB RAM.
  • Upstream contributions to LinkedIn Liger Kernel, AMD ROCm, and PrunaAI.
CloudCosmos Jul — Sep 2025 North Carolina, USA
Software Engineering Intern
  • Accelerated a financial reconciliation pipeline 33.0s → 3.6s (9.1×) through compute and memory optimization.
  • Built text segmentation and information extraction for Sanskrit literature and architectural design documents.
Stealth Startup Mar — Apr 2025 India · Freelance
Freelance Machine Learning Engineer
  • Fine-tuned domain LLMs on federal immigration documents to auto-generate appeal drafts with precedent-based citations.
  • Improved an IELTS predictor R² 0.86 → 0.97 and shipped a 90%-accuracy visa approval prediction system.